AI Model Deployment & Optimization on SoCs
AI Model Deployment & Optimization on SoCs
We optimize and deploy AI models on leading automotive SoCs from NVIDIA, Qualcomm, TI, and others. With a deep understanding of SoC architectures, we allocate tasks across hardware IP blocks such as GPU, DSP, and dedicated AI accelerators to get the most out of the hardware. From high-end SoCs with hundreds of TOPS to edge SoCs with just a few TOPS, we deliver production-ready perception systems.
Key Techniques
- Identifying and resolving bottlenecks using a range of profiling tools
- Optimizing task allocation across hardware IP blocks and pipeline design, based on the characteristics of the AI model and its pre- and post-processing
- NVIDIA (DRIVE AGX Xavier/Orin/Thor, Jetson, etc.): ONNX-to-TensorRT conversion and optimization through CUDA implementation
- Qualcomm (QRB5165, QCS6490, etc.): ONNX-to-SNPE conversion and partitioned execution across GPU and DSP
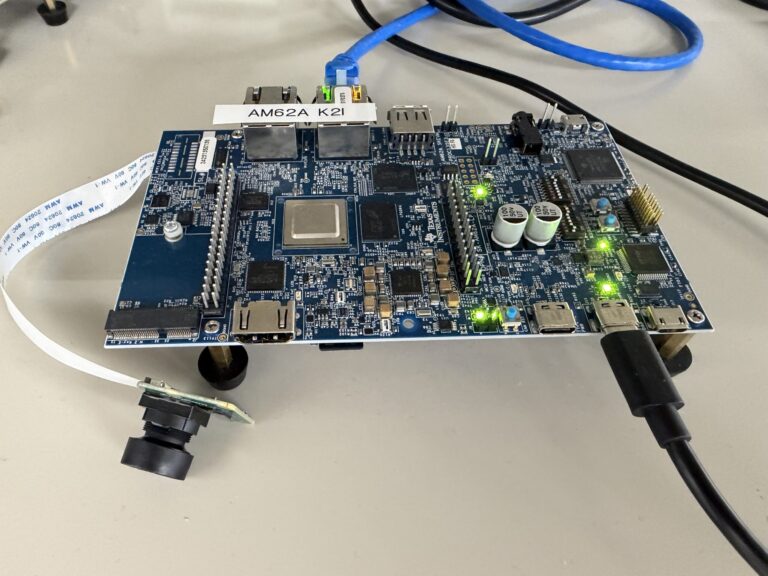
- TI (TDA4VM, TDA4VEN, AM62A, etc.): ONNX-to-TIDL conversion and DSP-based optimization
FEATURES
Deployment Experience Across NVIDIA, Qualcomm, and TI SoCs
We have a track record of deploying AI models on SoCs from NVIDIA, Qualcomm, and TI, each a leading automotive SoC vendor. Starting from ONNX, we apply each vendor’s conversion and optimization toolchain, including TensorRT, SNPE, and TIDL, and handle everything from evaluation board bring-up and BSP installation to system-level evaluation, optimization, and benchmarking.
Optimizing Workloads Across Hardware IP Blocks
We offload AI models and their pre- and post-processing to multiple dedicated hardware IP blocks, such as GPUs and dedicated AI accelerators, based on the characteristics of each workload. By optimizing the pipeline as a whole, we build systems that meet strict real-time requirements. Using open-source and vendor-provided profiling tools, we identify and resolve bottlenecks in CPU core load, interrupts, and memory transfers to unlock the full performance of the SoC.
Production-Ready Perception on Resource-Constrained Hardware
We build production-ready perception systems even on 2-TOPS-class SoCs, which have hundreds of times less compute than SoCs designed for autonomous driving. On the TI AM62A74 (2 TOPS), we have run multiple tasks, including object detection, lane detection, traffic sign and traffic light recognition, and distance estimation, at 15 FPS simultaneously. By combining architectures designed around inference cost with knowledge distillation, we make it possible to bring products to market under tight cost constraints.